How Does the Python Scraping Infrastructure Our Team Built Work?
\n
Programmatic SEO (pSEO) is a method of automatically generating thousands of pages with data and templates instead of writing them manually. But the lifeblood of this method is accurate and up-to-date data. If there is no data, or if it is low quality, the templates don’t matter at all.
\n
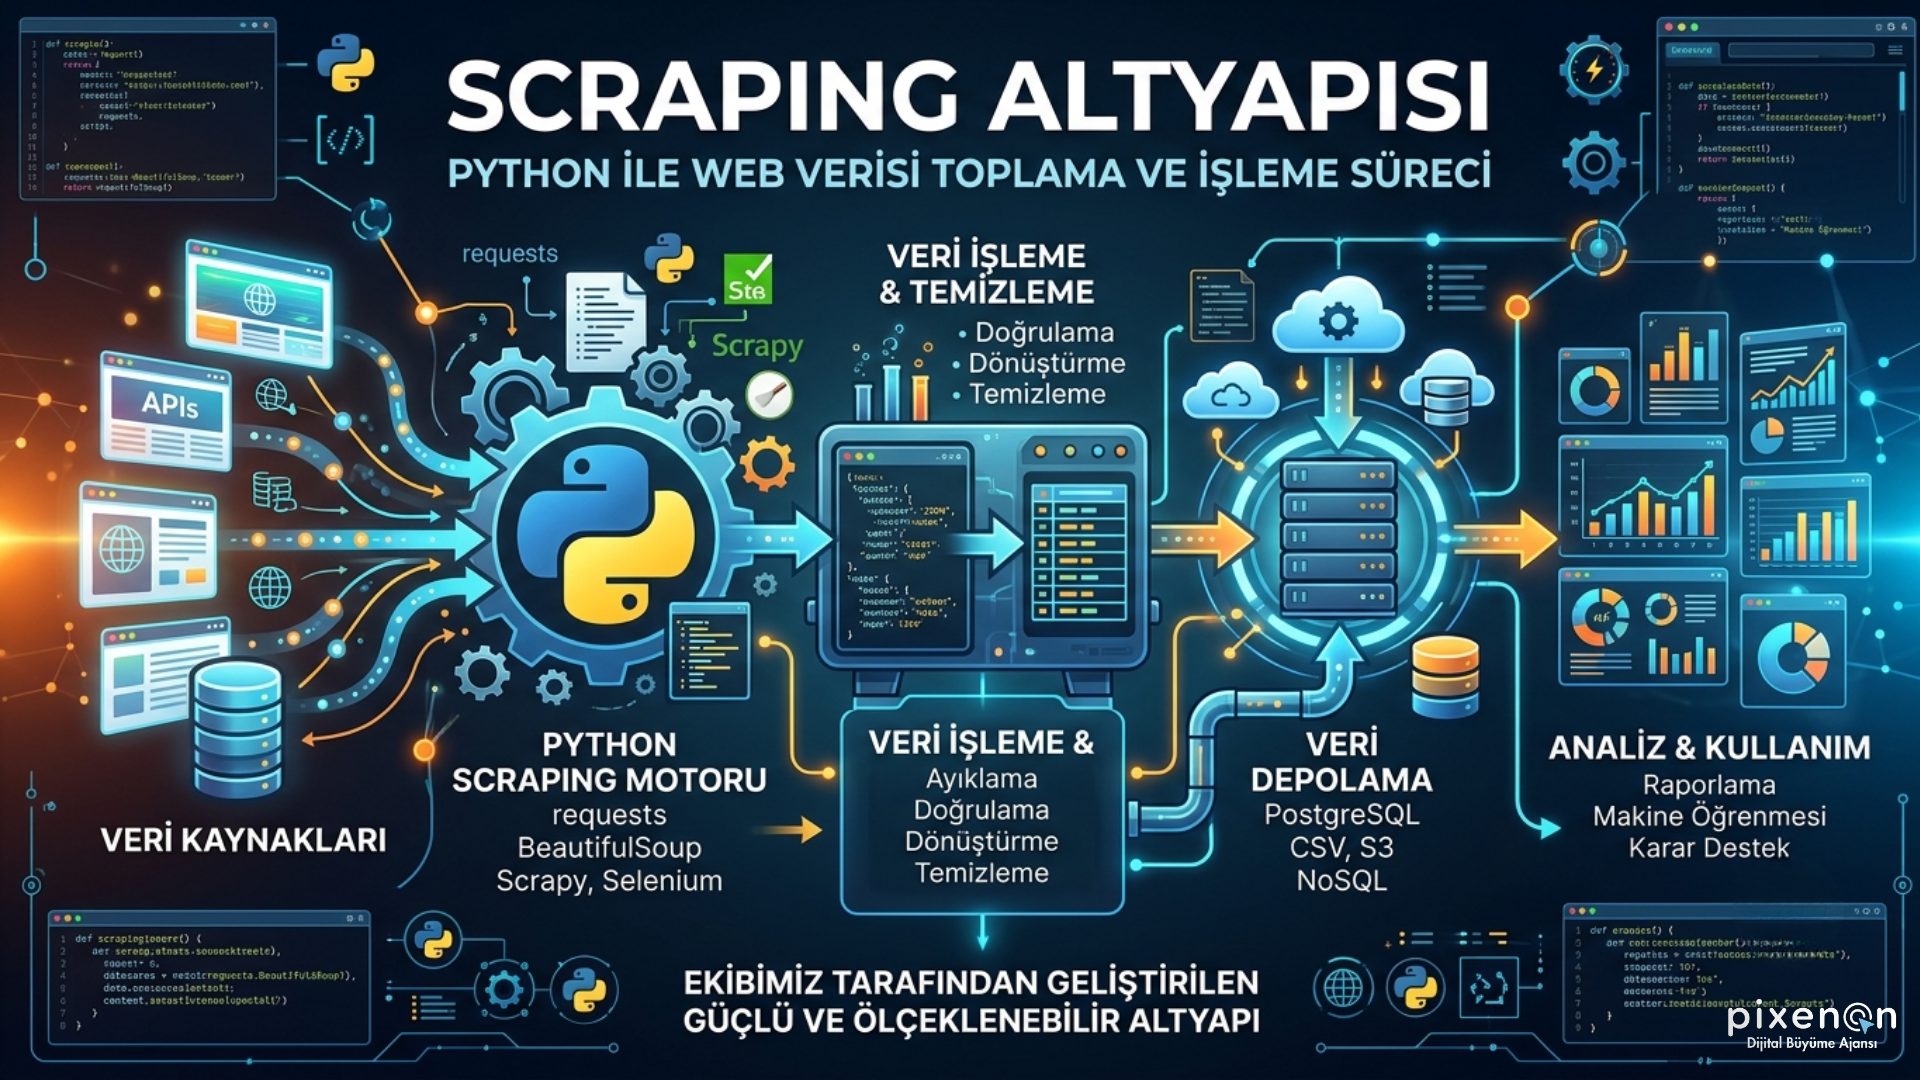
At Pixenon, in our pSEO projects we mostly source the data that feeds the content templates from two places: the client’s own database and the open web. To reach the second source, we set up a Python-based scraping infrastructure.
\n
\n
Why Python?
\n
There are multiple tools in the scraping world: ready-made platforms like Apify, Scrapy Cloud, Bright Data; alternatives like Node.js-based Playwright or Puppeteer. We choose Python because:
\n
\n
-
\n \t
- Rich ecosystem:
requests,httpx,BeautifulSoup,Playwright,Selenium— all are mature libraries in Python. - Natural integration with data processing: We use Pandas, SQLAlchemy, and Pydantic for the cleaning, normalization, and loading steps after scraping. Python handles these three steps in a single language.
- Prevalence within the team: The data, SEO, and backend teams speak the same language; maintenance becomes easier.
\n \t
\n \t
\n
\n
The Three Layers of the Infrastructure
\n
1. Data Collection Layer
\n
We encounter two types of pages: pages that return static HTML and dynamic pages where JavaScript processes the content in the browser.
\n
For static pages:
\n
python
\n
\n
import httpx
\nfrom bs4 import BeautifulSoup
\n
\ndef fetch_static(url: str) -> BeautifulSoup:
\n    headers = {
\n        "User-Agent": "Mozilla/5.0 (compatible; PixenonBot/1.0)"
\n    }
\n    response = httpx.get(url, headers=headers, timeout=15)
\n    response.raise_for_status()
\n    return BeautifulSoup(response.text, "lxml")
\n
\n
\n
We use httpx because, compared to requests, it has async support; both synchronous and asynchronous requests can be made with the same interface. When crawling large lists, sending parallel requests with asyncio saves significant time.
\n
For dynamic pages:
\n
For pages that require JavaScript rendering (especially e-commerce and real estate sites), we use Playwright:
\n
python
from playwright.async_api import async_playwright

async def fetch_dynamic(url: str) -> str:
    async with async_playwright() as p:
        browser = await p.chromium.launch(headless=True)
        page = await browser.new_page()
        await page.goto(url, wait_until="networkidle")
        content = await page.content()
        await browser.close()
    return content
The wait_until="networkidle" parameter waits for the page to complete all of its asynchronous requests. In some projects, we replace it with "domcontentloaded" to save time; if the critical content loads into the DOM early, this is sufficient.
2. Data Cleaning and Normalization Layer
Data scraped from raw HTML rarely comes ready to use. Common issues:
-
\t
- Excess whitespace and special characters
- Inconsistent price formats (“1.200 TL”, “1200TL”, “1,200”)
- Missing fields (some products have no description)
- Encoding issues (especially on older sites containing Turkish characters)
\t
\t
\t
We use a Pydantic model for the cleaning step. It handles both validation and normalization at the same time:
python
from pydantic import BaseModel, validator
import re

class Product(BaseModel):
    name: str
    price: float
    description: str = ""
    category: str

    @validator("price", pre=True)
    def parse_price(cls, v):
        # "1,200.50 TL" → 1200.50
        cleaned = re.sub(r"[^\\d,]", "", str(v)).replace(",", ".")
        return float(cleaned)

    @validator("name")
    def strip_name(cls, v):
        return v.strip()
A scraper using this model automatically discards data with missing fields or fills it with a default value. We don’t pass dirty data downstream.
3. Storage and Integration Layer
Where does the collected and cleaned data go? It depends on the project:
Google Sheets integration (small and medium-scale pSEO projects):
If the content template for Webflow, WordPress, or custom CMSs is fed through Google Sheets, the scraper writes directly there. We provide access with service account credentials using the gspread library.
PostgreSQL / Supabase (large-scale projects):
When thousands of rows are involved, we use a relational database. We set up the ORM layer with SQLAlchemy; Alembic for migrations. In projects where we prefer Supabase, we can also fetch data via the REST API — this is especially useful in headless CMS architectures.
Airtable (in some client projects):
If the client’s team needs to view or edit the data themselves, Airtable is a good fit. We automate write operations with the Python API client.
Rate Limiting and Ethical Scraping
Overloading a site is neither ethical nor free of the risk of an IP ban. Our infrastructure has several layers:
Request intervals:
python
import asyncio
import random

async def polite_fetch(url: str):
    await asyncio.sleep(random.uniform(1.5, 3.5))  # random delay
    return await fetch_dynamic(url)
Instead of a fixed delay, we use a random interval; this makes bot detection harder.
Retry mechanism:
We handle transient errors (connection timeout, 429 Too Many Requests) with the tenacity library:
python
from tenacity import retry, wait_exponential, stop_after_attempt

@retry(wait=wait_exponential(min=2, max=30), stop=stop_after_attempt(4))
async def fetch_with_retry(url: str):
    return await fetch_dynamic(url)
robots.txt check:
Before the scraper starts, we check the target site’s robots.txt file. The urllib.robotparser in Python’s standard library is sufficient for this job.
Orchestration: How Are Tasks Scheduled?
Rather than one-off scraping, most pSEO projects require periodic data updates. Prices change, new products are added, stock status varies.
We use two approaches for this job:
Small scale: GitHub Actions. A workflow defined in YAML triggers the Python script at specific times. Simple, free, and easy to maintain.
Medium-to-large scale: Prefect or Airflow. We manage dependent tasks with a DAG (Directed Acyclic Graph) structure: first the category list is fetched, then the products within each category are fetched in parallel, followed by the cleaning and loading steps. On failure, an alert is sent and the failed step is retried.
A Real Scenario: Local Service pSEO Project
For a service-sector client, we set up a pSEO project that automatically converts “city × service” combinations into a content template. Example: thousands of keywords like “Izmir cleaning company,” “Ankara lease agreement.”
The purpose of the scraping step in this project is this: to analyze competitor results for each city and determine which data points should appear on the page (average price range, frequently searched sub-services, user questions, etc.).
The process works like this:
- Target keywords are read from a CSV or Airtable.
- If Google SERP data is needed for each keyword, legal APIs such as SerpAPI or ValueSERP are used (Google’s TOS prohibits direct SERP scraping).
- Structural content on competitor pages — headings, question blocks, schema data — is extracted with BeautifulSoup.
- This data is cleaned with Pydantic models and loaded into Supabase.
- The content template is fed from this table to generate a unique page for each URL.
What Is Not Done?
Writing this section is important because the scraping infrastructure has limits:
- Content requiring login: Data behind a login wall cannot be obtained through scraping. Crossing this boundary violates the site’s terms.
- Real-time pricing: For instant price data, direct API integration should be preferred over scraping. Scraping produces latency and inconsistency.
- Large media files: Images and videos are outside the scope of scraping; we set up a separate pipeline for these.
Summary
Pixenon’s Python scraping infrastructure consists of the following components:
| Layer | Tools |
|---|---|
| HTTP requests | httpx, requests |
| Dynamic rendering | Playwright |
| HTML parsing | BeautifulSoup, lxml |
| Data validation | Pydantic |
| Retry and resilience | tenacity |
| Storage | PostgreSQL / Supabase / Google Sheets |
| Orchestration | GitHub Actions / Prefect |
This infrastructure is a tool, not a goal. The point where scraping creates value is when the extracted data reaches the pSEO templates accurately and cleanly. When data quality drops, page quality drops too, so we allocate at least as much time to the cleaning layer as to the collection layer.