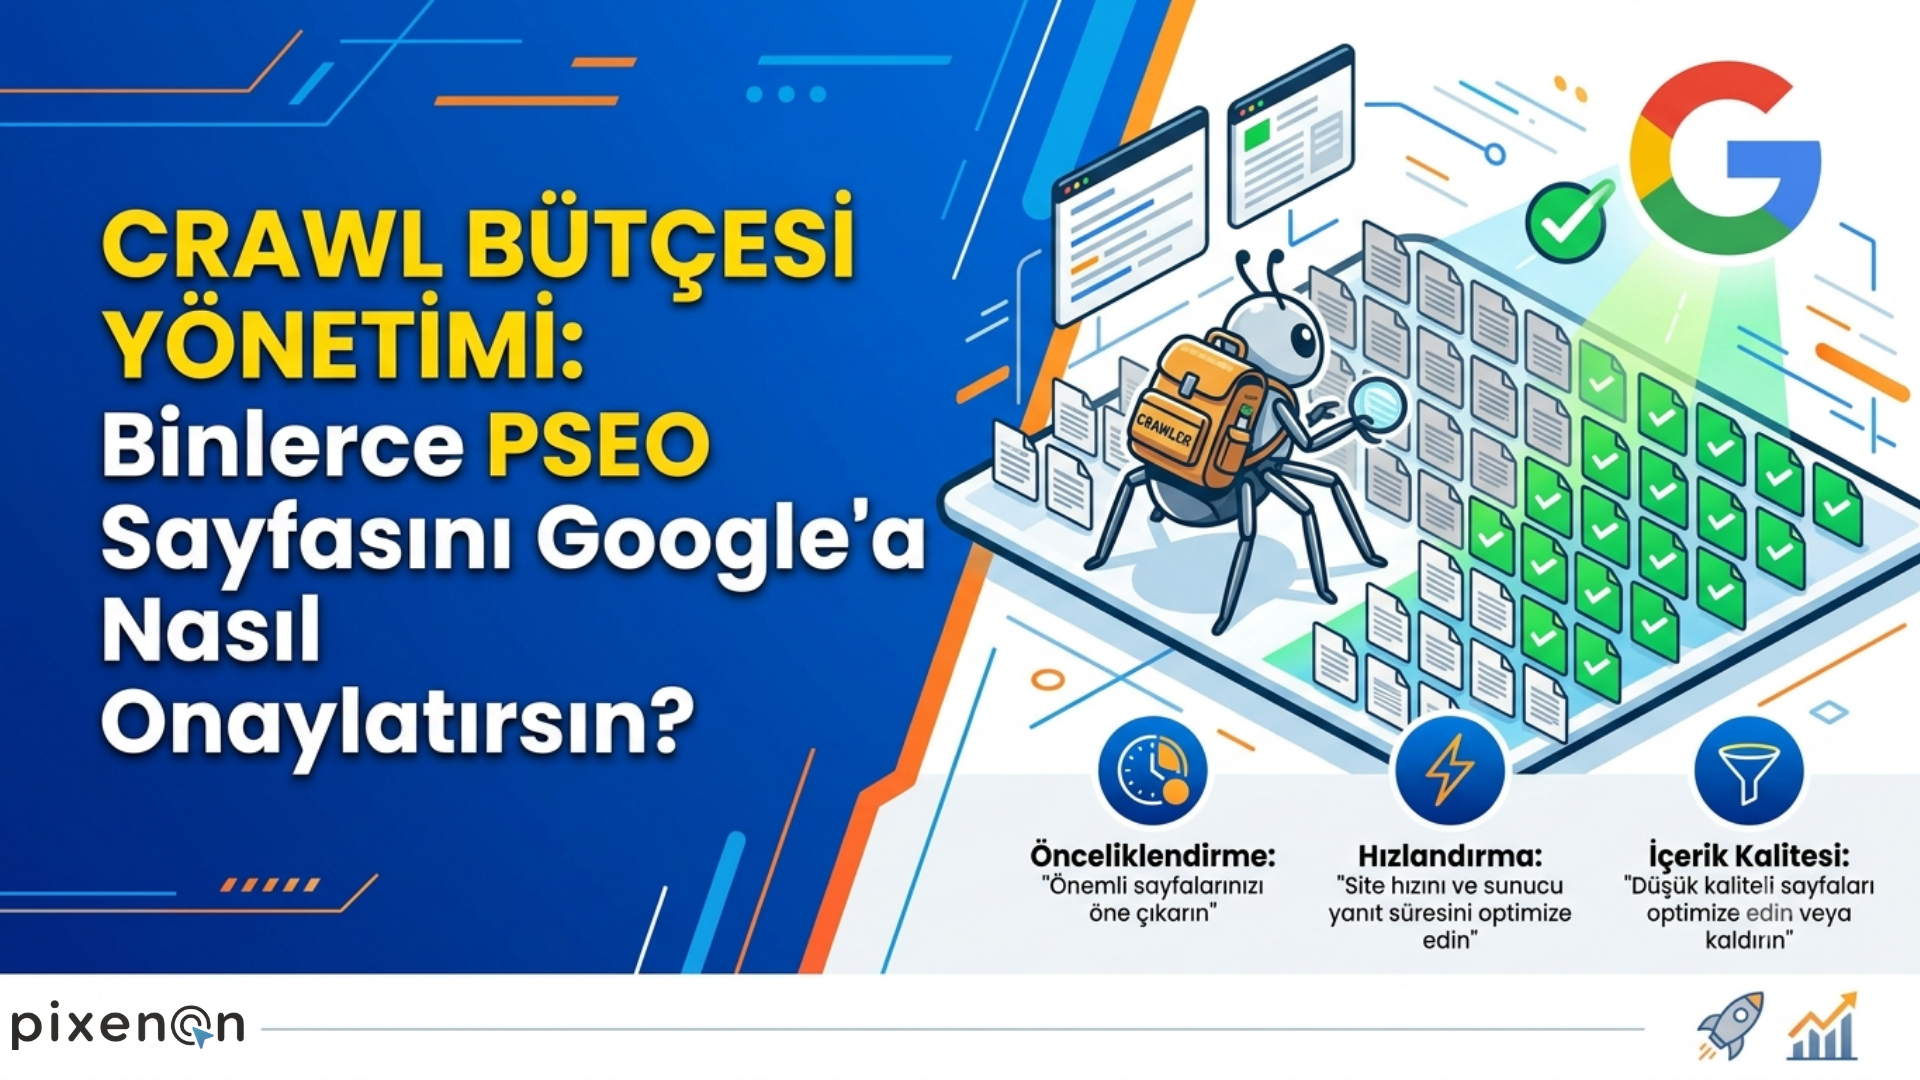
Crawl Budget Management: How Do You Get Thousands of PSEO Pages Approved by Google?
\n
Pixenon Digital Growth Agency
\n
The most common frustration in Programmatic SEO (PSEO) projects is this: you publish 10,000 pages, a few weeks later you open Search Console and most of your pages are sitting in the “Discovered – currently not indexed” or “Crawled – currently not indexed” category.
\n
The content isn’t bad, the technical infrastructure is working, but Google has never visited most of the pages or has visited them and decided not to index them.
\n
This is a crawl budget problem before it is a content quality problem. And in large-scale PSEO projects, these two problems easily get mixed up. In this article, we separate the two and explain the why and the solution step by step.
\n
\n
What Exactly Is Crawl Budget?
\n
According to Google’s official definition, crawl budget is the amount of time and resources Googlebot allocates to crawling a site. It consists of two main components:
\n
Crawl capacity limit: How many concurrent connections Googlebot can use without overloading your server, and the wait time between requests. If the site responds quickly, this limit rises and more connections can be used; if the site slows down or returns server errors, the limit drops and Google crawls less.
\n
Crawl demand: How much Google cares about that site. Googlebot’s demand varies depending on the size of the site, how frequently it is updated, page quality, and relevance relative to other sites. Three factors determine this:
\n
\n
-
\n \t
- Perceived inventory: Without direction from you, Google tries to crawl all the URLs it knows about. If many of these are duplicates or you don’t want them crawled, this causes Google to waste a large portion of its crawl time, and this is the factor you can control the most.
- Popularity: URLs that are more popular on the internet are crawled more frequently to be kept fresher.
- Staleness: Systems want to re-crawl often enough to catch changes.
\n \t
\n \t
\n
\n
An important point: even if the crawl capacity limit is not fully used, if crawl demand is low, Google will crawl your site less. So strengthening your server alone is not enough; you also need to send Google the signal that “this content is important, crawl me more often.”
\n
Another critical distinction: not everything that is crawled will necessarily be indexed; after each page is crawled and consolidated, its eligibility for the index is evaluated.
\n
In other words, crawl and index are two separate gates. In PSEO, the real problem is often not that pages are never crawled, but that they are crawled and then deemed “not worth indexing.”
\n
\n
When Should You Take This Seriously?
\n
Google clearly defines who this guide is for. The guide is specifically for these types of sites: large sites with 1 million+ unique pages whose content changes at a moderate frequency (once a week); medium or large sites with 10,000+ unique pages whose content changes very quickly (daily); and sites with a high proportion of URLs classified in Search Console as “Discovered – currently not indexed.” Google also adds that these numbers are not exact thresholds but are for rough classification.
\n
For a PSEO project operating in the Turkish market, the practical equivalent is this: a pilot of 500-1,000 pages falls outside this, but a structure that grows to 5,000+ pages and adds new city/product/category pages weekly is exactly the target audience of this guide.
\n
If your site doesn’t have a large number of rapidly changing pages, or if your pages appear to be crawled the day they are published, you don’t need this guide; keeping your sitemap up to date and regularly checking index coverage is enough. In other words, before diving into crawl budget optimization, you need to confirm whether there really is a problem.
\n
\n
5 Classic Mistakes That Consume Crawl Budget in PSEO
\n
Template Variation Is Not Content Variation
\n
The logic of PSEO is to fill a template with thousands of data combinations, such as “SEO Agency in Istanbul,” “SEO Agency in Ankara,” “SEO Agency in Izmir.” The problem arises when the template stays the same and the only real difference between pages is the city name. In this case, Google reads thousands of pages as a single “pattern” and lowers crawl demand.
\n
The core update in March 2026 sent a clear signal on this: Google’s March 2026 core update explicitly labeled scaled content abuse as a violation.
\n
Sites that produced thousands of nearly identical pages through AI or template automation without real added value experienced a 60-90% ranking loss overnight.
\n
By contrast, PSEO with real data differentiation survives: local business directories with verified listings, comparison tools with live pricing, and travel guides with real inventory data continue to rank.
The threshold is whether each page answers a distinct user query that no other page on the site answers.
Practical takeaway: When setting up a PSEO template at Pixenon, we add at least one non-template paragraph to every page a short editorial comment, use case, or real data point.
Industry practice summarizes it this way: every page needs at least one paragraph not generated from the template it can be a short editorial comment, a use case anecdote, a case study reference, or a perspective from someone on the team.
It doesn’t need to be long; 250 words of unique narrative is enough to elevate a page from “template” status to “template with real human input.” On priority pages, this turns into a 600-1,200 word editorial layer on top of the template structure.
Faceted Navigation and Parameter Explosion
In e-commerce-heavy PSEO (such as product × color × size × sort), the number of URLs grows exponentially. A single category with 50 products, 5 color options, 4 size options, and 3 sort orders produces 3,000 unique URL combinations. Across thousands of categories, this creates millions of nearly identical parameter URLs filling up the crawl queue.
The order of solutions should be as follows:
- Use rel=canonical on parameter URLs pointing to the clean URL.
- Make sure internal links point to canonical URLs, not parameter URLs.
- Block filter combinations that genuinely add no value for users (such as “sort: price ascending”) via robots.txt.
Confusing “Crawled Currently Not Indexed” with “Discovered – Currently Not Indexed”
These two statuses point to different problems and require different solutions:
Discovered currently not indexed: Google knows the URL exists (from the sitemap or an internal link) but hasn’t crawled it yet. This is typically a crawl budget or queue issue.
Crawled currently not indexed: Google has already evaluated the page and deliberately decided not to index it. In this case, the issue is no longer crawling but quality perception.
Chasing “more crawl budget” without making this distinction is a waste of time if the problem lies with pages that have already been crawled but rejected, the solution is not speeding up the server but strengthening the content/quality layer.
One caveat when reading this report in Search Console: Page Indexing report data is generally updated more slowly than the URL Inspection tool; there can be a delay of a few days.
Right after fixing a page, the report may still show the old status before panicking, it’s necessary to verify individually with URL Inspection.
4. Site Quality Perception Also Affects Individual Pages
This is the most overlooked point. The most surprising reason is this: a page may not be indexed because Google isn’t convinced about the overall quality of the site.
In other words, if you publish 8,000 weak PSEO pages, the 200 genuinely good pages among them can also suffer from this “bad neighborhood” effect.
That’s why at Pixenon we never do large-scale PSEO launches all at once. The industry-accepted phased approach works like this:
Phase 1: 50-100 high-confidence pages. Publish the highest-priority permutations first. Monitor indexing, impressions, and rankings for two to four weeks.
The goal is to verify the template works before scaling.
Phase 2: 500-2,000 pages, expand to the next slice when the indexing rate is above 80% and most pages have measurable impressions.
Phase 3: full rollout.
The rationale for this gradual approach is also backed by a concrete case: when validation isn’t done before scaling, disasters can happen where only 312 of 8,000 pages rank, while the rest either get indexed and remain invisible, get deindexed by Google, or get stuck in the Crawled-currently not indexed bucket.
AI Bots Sharing Server Load
A new dynamic in 2026: it’s no longer just Googlebot; a large number of AI crawlers are also sharing server capacity. GPTBot, CCBot, Google Extended, and other AI crawlers crawl the site independently and can consume up to 40% of available bandwidth during deep crawl cycles.
This extra consumption has a side effect: it can suppress the effective crawl rate limit by reducing server availability for Googlebot.
\n
The first solution that comes to mind in return is not free: sites that block GPTBot were cited 73% less in ChatGPT responses.
\n
In other words, for brands that care about AI visibility, this decision needs to be evaluated not only in terms of server load but also in terms of GEO (generative engine optimization) strategy.
\n
\n
Step-by-Step Implementation Plan
\n
Step 1: Manage Your URL Inventory
\n
Google’s own advice is clear: consolidate URLs and focus on unique content rather than unique URLs.
\n
Block unimportant pages with robots.txt, for example infinite scroll pages or differently sorted versions that repeat the same information as linked pages.
\n
There is a critical warning here: do not use noindex, because when Google sees a noindex meta tag or header in the response, it will still request the page, then drop it, and this will waste crawl time. Do not use robots.txt to temporarily reallocate crawl budget to other pages; use robots.txt to block pages you do not want crawled at all.
\n
Google will not shift this newly freed crawl budget to other pages unless your site has already reached its serving limits.
\n
\n
Step 2: Use 404/410 for Permanently Deleted Pages
\n
Google does not forget a URL it knows, but a 404 status code is a strong signal that the URL should not be crawled again. Blocked URLs, on the other hand, stay in the crawl queue much longer and are recrawled when the block is lifted.
\n
\n
Step 3: Clean Up Soft 404s
\n
Soft 404 pages continue to be crawled and waste your budget. Check for soft 404 errors in the Index Coverage report. In PSEO, this is especially common on pages that return an empty template in the “no data found” case but give a 200 status code, for example an out-of-stock product or a city page with no listings at all.
\n
\n
Step 4: Segment Your Sitemap and Keep It Up to Date
\n
Google reads your sitemap regularly, so make sure you include all the content you want crawled. If you have updated content on your site, we recommend adding the lastmod tag.
\n
However, using this tag unrealistically backfires: sites that update all lastmod dates every day train Google not to trust their signals, the exact opposite of what is intended.
\n
In large PSEO projects, using separate sitemap files by content type (products, categories, city pages, blog) makes it possible to monitor crawl/index rates by type separately in Search Console.
\n
\n
Step 5: Avoid Redirect Chains
\n
Avoid long redirect chains, because they have a negative effect on crawling. In PSEO projects where the URL structure changes frequently (for example when the slug format is revised), these chains accumulate, so periodic redirect map cleanup is essential.
\n
\n
Step 6: Improve Page Load Speed and Renderability
\n
If Google can load and render your pages faster, we can read more content from your site. PSEO pages rendered client-side with JavaScript (especially incorrect SSR configuration in React/Next.js-based projects) can cause Googlebot to never see the content, which is perceived as “crawled but content empty” and leads to exclusion from the index.
\n
\n
Step 7: Two Ways to Actually Increase Crawl Budget
\n
Google reduces this clearly to two options: if your site cannot be crawled due to server capacity (for example, if you get a “Hostload exceeded” error in the URL Inspection tool), add more server resources if it makes sense for your business.
\n
On the other hand, optimize the quality of your content according to the Google product you are targeting; for Google Search, this includes factors such as popularity, overall user value, content uniqueness, and presentation capacity.
\n
So technical infrastructure alone is not enough; Google needs to see your site as “worth the crawl effort.” This brings us back to the core question of PSEO: does every page really offer unique value?
\n
\n
Realistic Expectations: PSEO in Numbers
\n
Nothing is as important as expectation management when starting PSEO. Field data shows the following:
- One of the best practices is Wise’s currency converter pages: 260,000 pages → 46 million monthly visits = ~177 visits per page (best in the industry).
- Zapier’s integration pages: 50,000 pages → 5.8 million visits = ~116 visits per page. Zapier also has 800,000+ pages indexed — the largest known PSEO implementation.
- A more modest but realistic example: Canva’s color palette pages: 1,900 pages → 83,000 monthly visits = ~44 visits per page. This is a good PSEO result that is published, indexed, and ranks for long-tail terms.
But the other side of the coin is this: the top 20% of typical PSEO output drives more than 80% of traffic. The bottom 50% usually attracts zero search engine clicks.
So publishing 5,000 pages and expecting all of them to bring traffic is not realistic, but the goal is to find the right 1,000 pages and systematically build the rest without lowering the quality of those pages.
The Pixenon Approach: Managing Crawl Budget as a Strategic Asset
Crawl budget management should not be treated as a “technical detail to be fixed later” in PSEO projects, but should be designed from the start as part of the content strategy. At Pixenon, our approach to large-scale PSEO projects follows this order:
- Validate the data layer is there a real, updatable, unique data source that can fill the template?
- Prove it in the pilot phase monitor indexing rate, impressions, and ranking signals in a 50-100 page slice.
- Reset the technical infrastructure canonical, sitemap segmentation, redirect map, render performance.
- Launch in stages do not move to the second slice until the indexing rate is proven.
- Verify with log files instead of relying on Search Console, monitor actual Googlebot behavior from server logs.
When a PSEO architecture of thousands of pages is set up correctly, crawl budget stops being a constraint and turns into a sustainable organic traffic engine.
When set up incorrectly, even the highest-quality content continues to go unnoticed by Google.